Posts

Is It Alpha or Is It Luck?

My post on Moral Hazard in Asset Management reminded me of a great paper by Foster & Young (“Gaming Performance Fees by Portfolio Managers,” QJE 2010). They showed that if an asset manager can sell options1 then it is impossible to distinguish skill from luck based on a manager’s track record. In fact, if – as is often the case – managers are compensated for positive track records, then there is a glaring incentive for unskilled managers to compete for assets by taking hidden risks.

What’s the problem?  Let’s start with the traditional hedge fund pitch: A skilled manager finds a way to produce alpha – for the purposes of this post, alpha can be described as profits beyond what can be earned from passive exposure to market investments.  Call the legitimately skilled manager a “Maker” of alpha.2  Whatever alpha a Maker produces can be mimicked using skewed contracts that have no alpha.  An unskilled “Mimic” manager can create the appearance of alpha by tucking offsetting risk in a tail of his return distribution.  And you can too, using this little Mimic calculator:

How a stellar track record can hide a cliff

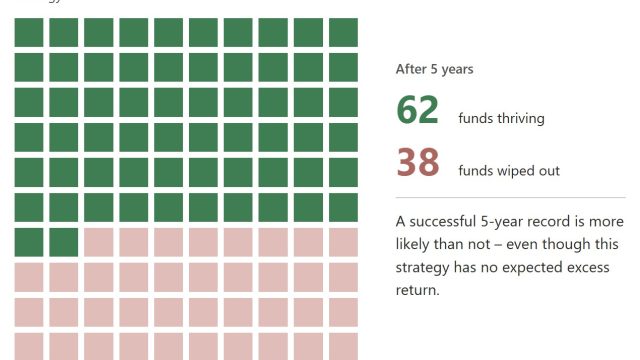
Here we model 100 Mimics who use a simple gamble to produce the appearance of skill.

Pick the annual return to mimic, then dial the length of the track record to see how many unskilled Mimics would stay in business at least that long.

Excess annual return in a successful year 10.0%
2% 30%
Track record 5 years
1 year 10 years

Expected excess return: 0%. Annual probability of total loss: 9.1%

Each square represents one Mimic fund following the same strategy.

After 5 years

62 funds thriving
38 funds wiped out

A successful 5-year record is more likely than not – even though this strategy has no expected excess return.

How does the expected excess return stay at zero?

For an excess annual return of 10.0% in a successful year, the annual chance of a total loss is 9.1%. The two numbers are linked so the usual gains exactly offset the rare loss:

loss chance = gain / (1 + gain) (1 − loss chance) × (1 + gain) = 1

The chance of succeeding for 5 years is 62.1%.

How could an option create this payoff?

In an idealized, zero-interest example, start with $1, sell a one-year cash-or-nothing put whose payoff is $1.1000 if a specified event occurs. If the put expires worthless, the stake becomes $1.1000; if it pays, the stake becomes $0. (To fund this at a $1 starting cost, the put must fetch $0.09091 per $1 of contingent payoff.)

Since a hedge fund manager typically sells alpha (i.e., excess returns), the benchmark rate of return cancels out of the equations underlying this model.

A deliberately simple strategy: each path either gains steadily or suffers a total loss. It assumes independent loss events, and event options that trade at their expected value with no transaction costs.

As this toy example shows, each Mimic stands a decent chance of thriving for years without a positive expected return.  Just rolling the dice.3 Investors only meet the survivors, and the surviving Mimics collect management fees the whole time.

Mimics need not be malicious.  They could instead be naive or incompetent.  An example: Early crypto investors who milked arbitrage opportunities that looked like risk-free money … only if they didn’t account for counterparty risk.

Alpha need not exist.  In theory we know that as markets increase in efficiency, scalable alpha decreases.  In practice we know that alpha tends to evaporate: There are a lot of smart and motivated people looking for alpha, so the first person to find a source is never going to be the last, and as more people discover it the alpha is either driven to zero or it becomes beta.4

Solve for the equilibrium:  The supply of alpha is limited, transient, and unknown.  The supply of capital looking for alpha is effectively all of it.  If somebody claims that they will sell alpha to an outsider, the first question I ask is, “Why?”5  In the limit, a manager with real alpha can demand to keep virtually all of it because there is so much money chasing alpha.

What if investors avoid managers who can trade high-skew contracts?  This does help, and industry regulators have long tried to prevent retail funds from holding – or at least concealing – “speculative” risks like those needed to mimic alpha. That reduces the magnitude of the problem even though it doesn’t eliminate it. Retail investors are notorious for chasing historical performance. And any active manager can benefit from luck instead of skill to beat his benchmark by a few points and win significant assets in the process.

How do sophisticated investors address the Mimic problem?  They try to make mimicry more difficult by demanding more transparency and manager oversight. A stellar track record can attract attention, but prospective managers need to back it up with a strategy that can explain it and audits that show their activity is consistent with their disclosures. Fee design alone can’t do it: Foster & Young’s paper shows that postponing bonuses and clawing them back – the fix I proposed in Moral Hazard – will not stop Mimics unless it comes with transparency into managers’ positions and strategies. Is it alpha or is it luck? The track record alone can’t tell you.

  1. To be precise: a sufficient condition is access to contracts with highly skewed payoffs. ↩︎
  2. Alpha is worth paying for, and there are any number of ways skilled managers can generate returns on capital that are uncorrelated to the market and that have attractive expected return characteristics – arbitrage; market making; astutely harvesting market premiums on liquidity, information, and risk.  The problem Foster & Young rigorously demonstrate is that a “mimic” can sell options to create a negatively skewed stream of returns that, with high probability, is hard to distinguish from alpha … until it suffers a catastrophic loss. ↩︎
  3. There is some hand-waving going on here, but not much: In practice the risk/return utility function is not flat, and tail risks tend to command a risk premium, so the Mimic may earn a risk premium.  But that premium falls out of the equation by definition when we put things in alpha terms: no manager skill is needed to collect a risk premium that is available passively. ↩︎
  4. If competition for an alpha source doesn’t drive it to zero, then competition will turn it into beta. For example: 50 years ago a fund manager who bought stocks that were fundamentally cheap or had strong relative performance did in fact produce alpha.  Today there are strong arguments that those factors are fully priced into the market (i.e., the alpha went to zero), but if you disagree then you can buy those factors in ETF form almost for free (i.e., it has become beta). ↩︎
  5. There can be good answers, but they depend on details out of scope here. ↩︎
Moral Hazard in Asset Management

Compiled from posts I first published in 2006 and 2007.

There is a moral hazard for investment managers to take big risks: They are gambling with other people’s money. Fund managers share proportionately in the profits when they succeed, but do not share directly in the losses when they fail.

For example, active mutual fund managers are generally benchmarked to an index of the security types they hold. They “succeed” to the degree that they outperform the benchmark. Success attracts more money, which brings in more management fees that flow to the managers’ pockets. Failure to beat the index tends to result in attrition of assets under management. But in the worst case a manager doesn’t lose money the way investors lose theirs. Thus, the incentives for a new manager who wants to make a fortune, but who doesn’t have any special ability to beat the market, is to take a gamble by building a portfolio that is riskier than the index.1

Suppose the manager has “won” the gamble and thereby attracted more capital. If the manager becomes complacent with the higher fees generated by that capital he might stop gambling. In that case, the investors who expected him to beat the index will just be owning the index – but will be paying excess management fees because their lucky manager has a “proven record” of beating the index. And that’s actually the better scenario: If the manager continues to gamble he will eventually lose (i.e., underperform the index), and the losses will be greater in dollar terms because the manager was gambling with more capital than before.

Hedge Funds Amplify the Hazard

Hedge funds exacerbate this hazard because they can take enormous risks, and the payoffs to managers from big wins are realized quickly. One would hope that after a hedge fund manager blows up with an unjustified gamble that would be the end of his career. An October 2006 Wall Street Journal article revealed that such a hope may be in vain:

Brian Hunter, the natural-gas trader behind last month’s massive losses at hedge fund Amaranth Advisors, is exploring whether to get back in the game, people familiar with his plans say. … Amaranth, based in Greenwich, Conn., is liquidating, after Mr. Hunter’s bad bets triggered roughly $6.4 billion in losses, or 70% of its assets.

In 2005, Hunter personally banked roughly $75MM in performance fees for making enormous gambles with other people’s money. The next year he lost more than half his investors’ money and bankrupted his employer. Not only did he keep his fees on the prior year’s performance, but apparently there are still people out there who want him to gamble with their money.

Betting on fallen hedge-fund stars isn’t all that uncommon. John Meriwether, who led Long-Term Capital Management until its 1998 implosion, now runs another hedge fund.

The Status Quo

A common hedge fund structure pays managers a 2% management fee and, on top of that, 20% of profits. This emphasis on performance incentives is a hallmark of the industry. But the incentive is almost always implemented with a peculiar feature: The fund manager gets to lock in performance fees at the end of each calendar year. He keeps the rewards for a positive year even if he subsequently loses money for investors.

This fee structure creates perverse incentives. Because the manager shares directly in the upside, but risks nothing material on the downside, he has every reason to take excessive risks. The annual lock-in produces a behavior known as the Wealth Effect: Managers who have accumulated large profits tend to reduce risk towards the end of a calendar year in order to protect their impending payout. Managers who are underwater tend to “double-down” and take more risk, in hopes of recovering and turning a profit they can harvest at year end. In each case the manager’s incentives are not aligned with those of the investors, who expect a manager to steadily follow his advertised strategy and risk profile regardless of how much has been made or where they are in the calendar.

A common patch for this problem is to establish a “high-water mark” so that managers do not earn any incentives until they have entirely recouped losses. The perverse result of this is that as soon as their performance falls too much they tend to close up shop rather than stay in the game to recoup their investors’ losses. After all, there is no performance fee paid for recovering losses. Sometimes it is easier to start a new fund where they once again immediately share in profits. (This tendency for losers to quit has resulted in a notoriously large “performance selection bias” in the hedge fund industry.)

A Fix

The industry is ripe for an evolution in incentive structures: It is obvious that this needs to involve delayed vesting of performance fees. Performance fees should be kept in escrow with a vesting period much longer than one calendar year. (Just as the exact performance share varies from fund to fund, the vesting period could vary. A reasonable vesting period would be something like five years.)

So long as investor money is at risk, performance fees should be at risk. Granted, fund managers have to feed their families, so they would lock in their fees gradually over the vesting period. But delayed vesting will keep their skin in the game even if they have a big drawdown.

To see how this would ameliorate the hazards inherent in the current incentive structure, imagine a hedge fund named Zamaranth funded by two equal investors, A and B. During 2005 Zamaranth doubles its investors’ money, and the manager gets $100 million in incentive fees – escrowed, vesting over five years. Beginning 2006 the manager is earning $1.67 million each month from escrow – an ample payout from his stellar performance. If investor A cashes out, that money is no longer at risk and the manager immediately banks the escrowed fees: $50 million. A few months later, Zamaranth’s remaining positions collapse, losing all of the value they accumulated during 2005. Investor B, having lost all his gains, recoups all of the performance money remaining in escrow. The Zamaranth manager took a big risk, and he shared in the consequences. But he is still incentivized to work for his investor, because he is not “below water,” so any profits he earns will immediately accumulate in his escrow account.

20 years later

Europe pushed in this direction: The Alternative Investment Fund Managers Directive (AIFMD, 2013) effectively required at least 40% of performance fees to vest over at least 3 years. In the U.S., the closest such rule is Dodd-Frank Section 956, but it has not been put into effect.

Follow-up: Is It Alpha or Is It Luck?

  1. The mechanics of this gamble can vary in complexity. One simple approach: Hold every security in the index except for the lowest-risk ones. This modified portfolio will sometimes beat the index and sometimes underperform it – nobody knows in advance which, and even after the fact virtually nobody can tell whether the difference was due to skill or luck. ↩︎

Gold, the Fed, and the Tax on Inflation

Compiled from posts I first published in 2008 and 2010.

If you spend any time in anti-income-tax libertarian circles you will discover that fear and loathing of the IRS is followed closely by deep suspicion of the Federal Reserve (“Fed”) and abiding nostalgia for the days of the gold standard.  Libertarians spin vast conspiracy theories about who controls the Fed and who profits from it.  They appear to be confused.

The only solid argument I see against the Fed seems to circle back to the tax code, which presently levies taxes on inflation.  But this is an argument against the tax system, not the monetary system.

Yes, in principle the Federal Reserve could choose to inflate the money supply.  In an inflation scenario, non-debtor citizens holding dollars are harmed as dollars lose value.  Meanwhile our debtor government benefits since inflation not only reduces the (real, not nominal) national debt but also increases tax receipts from capital gains, thanks to the Tax on Inflation:  If you earn 5% interest during a period in which inflation runs at 5%, you have made no real gain on your savings.  However, the IRS currently looks at your gains in nominal, non-deflated terms, and so they will tax you as if you had gained 5%.

Gold-standard advocates see a commodity-backed currency as a solution to the moral hazard of government-instigated currency inflation.  But gold-backed currency is not immune to inflation or manipulation either: It simply replaces the intentional control of the money supply by the Fed with the circumstances of world-wide gold production and storage.  Inflation and deflation still occur when the production of new gold does not match the growth of the economy.  Nations and corporations could still manipulate the money supply by hoarding gold or flooding the market with their stores.  How is this any better than what we have right now?

Though in theory the Fed could take actions to inflate our currency, its mission is the exact opposite: to limit inflation.1  The Fed is also accountable to the banking system, and since banks are predominantly creditors they are not happy with inflation since it reduces the value of their credits.

There are numerous ways Americans can hedge against dollar inflation: Instead of storing dollars, hold hard assets, other currencies, or inflation-protected securities like TIPS.  One thing Americans can’t do at present is protect themselves from the Tax on Inflation: As long as the IRS demands that gains be calculated against an inflating currency, it can assess capital gains even when real gains are zero (or negative!).

Ironically, this argument feeds directly into the personal portfolios of many gold-standard advocates.  Often dubbed ‘gold bugs,’ these are people who have concluded that physical gold is the best hedge against inflation and fiat currency risks.  Gold bugs revel in the relatively stable historical value of gold.  One problem I have pointed out is that its intrinsic value (i.e., its substitution value as a material for industrial or other practical uses) is closer to that of lead or copper.  Its stratospheric market value is entirely a function of (1) scarcity and (2) speculation, which is to say that it trades where it does because buyers believe that there will continue to be other buyers ready to pay similarly elevated prices.  If everybody decided one day that they would rather own platinum jewelry and hoard casks of whiskey as a hedge against inflation then the price of gold could collapse to its substitution value.

The other problem is that the supply of gold is not fixed.  True, the cost of mining and refining has historically been proportional to industrial capacity.  The last technological breakthrough in production came in the 19th century with the MacArthur-Forrest Process for extracting gold from low-grade ore.  But even barring another breakthrough in production, the gold supply does increase with demand: When gold prices surge, capital investments in mining operations follow and the production of gold increases.

  1. Not exactly to zero, but rather to 2% per year – for macroeconomic reasons beyond the scope of this post. ↩︎

Why I Dislike Dark Mode

First published in my newsletter, September 4, 2023.

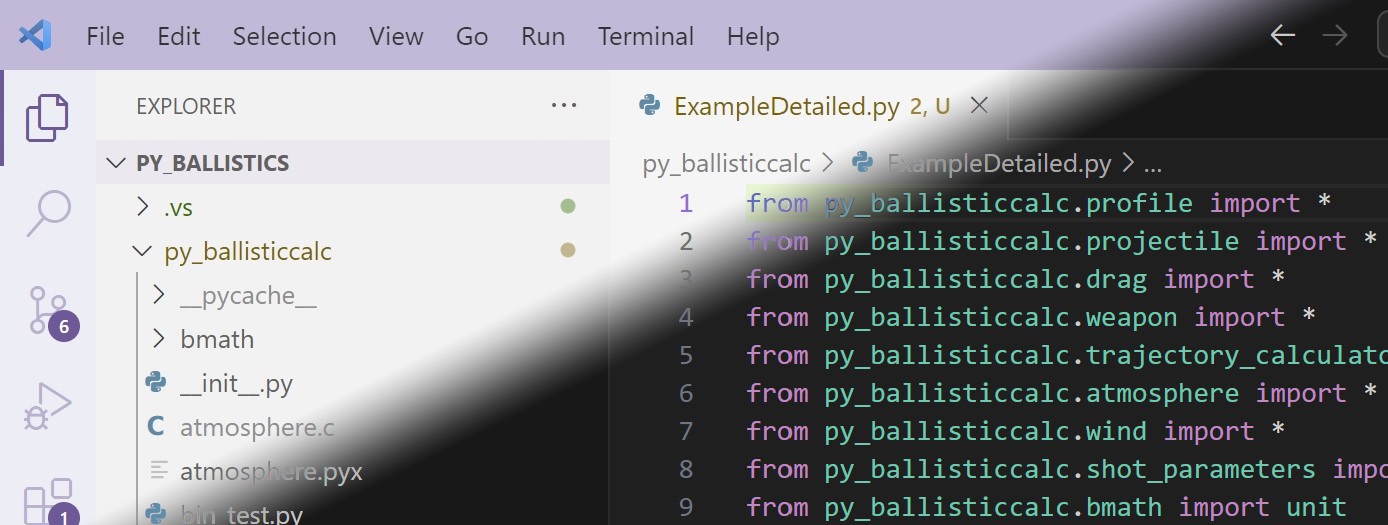
VSCode Light Theme vs Dark Theme

The Light Mode vs Dark Mode GUI question has become somewhat polarizing.  Increasing numbers of apps have added Dark themes that use a black background.  I generally prefer light mode for one very specific and widely applicable reason, even though I grew up with “dark” displays.

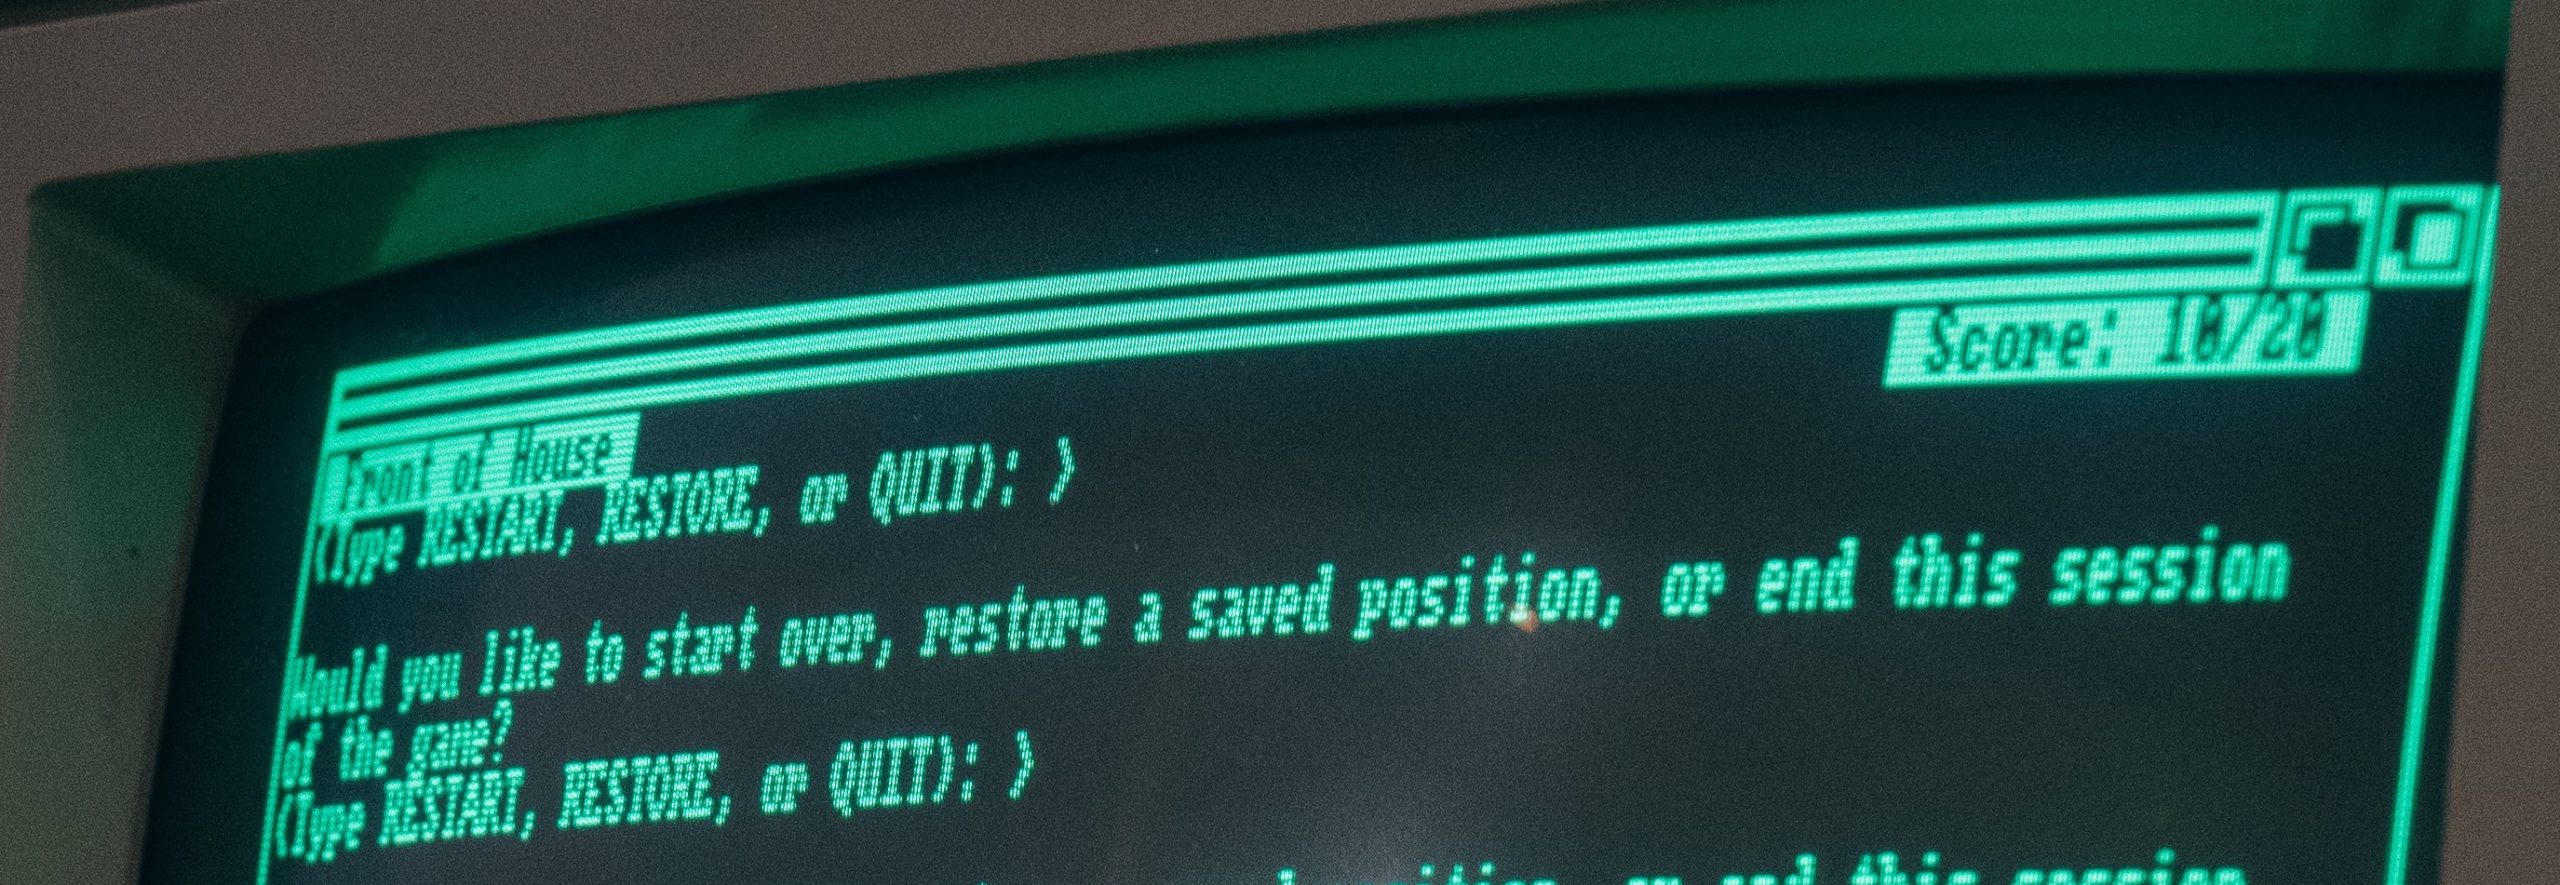
In the old days – back when all computer displays were cathode ray tubes (CRTs) and PCs only had enough memory to display 25 lines of 80 characters of text in a fixed font – screens were black with white, green, or amber text, like this:

1980s Monochrome CRT computer display

It was possible to invert these to show the text as black on light.  But as far as I remember, the first computer to mainstream a uniformly light background with black text was the 1984 Macintosh.  And I thought it was grotesque.  The pixels on those old monitors were not very sharp, so instead of bright text characters bleeding a little onto a black background, a white background seemed to accentuate the blurriness as it bled into the black text pixels.  (In fact, on color screens the individual red green and blue phosphors that made up each white pixel would stand out if viewed closely.)  For me, fewer illuminated pixels was better.

By the end of the 1980s, CRT monitors had significantly improved in both resolution and pitch, making everything more crisp and making light backgrounds more tolerable.  WYSIWIG became all the rage, and since most computer work was done to be printed on white paper GUIs defaulted to white backgrounds with black text – Light Mode.  There was also a lot of contemporaneous research, as detailed in this seminal article, that supported the idea that humans work better in Light GUIs.

However, even in the enlightened 1990s programmers spent their time in text terminal windows and development environments that to this day default to dark mode.  For example, in Windows open a command terminal by going to Start and typing “cmd”.  So I do have some nostalgia for the dark-mode days.

And then I grew into my mid-40s.  Most people in middle age will get presbyopia, which is a reduced ability to focus at close distances.  (This is due to a consistent decrease over time in the flexibility of the eye’s natural lens.)  I can no longer read small or dim text without reading glasses to push the focal distance further out.  And this is where light mode shines.

Photographers know that the wider the aperture of a lens, the more shallow the range of things that can be in focus (a.k.a., depth of field).  As the aperture closes, depth of field increases.  At the limit, a pinhole aperture has an infinite depth of field: everything is in focus no matter what its distance from the viewer.1

The same physics hold for eyes: the wider our pupils open, the more our lenses have to deform to shift focus, and the more apparent is any astigmatism.  As our pupils close more of our field of view comes into focus.  In fact, if you look through a pinhole everything will be in focus, no matter how extreme an eyeglass prescription you may have.

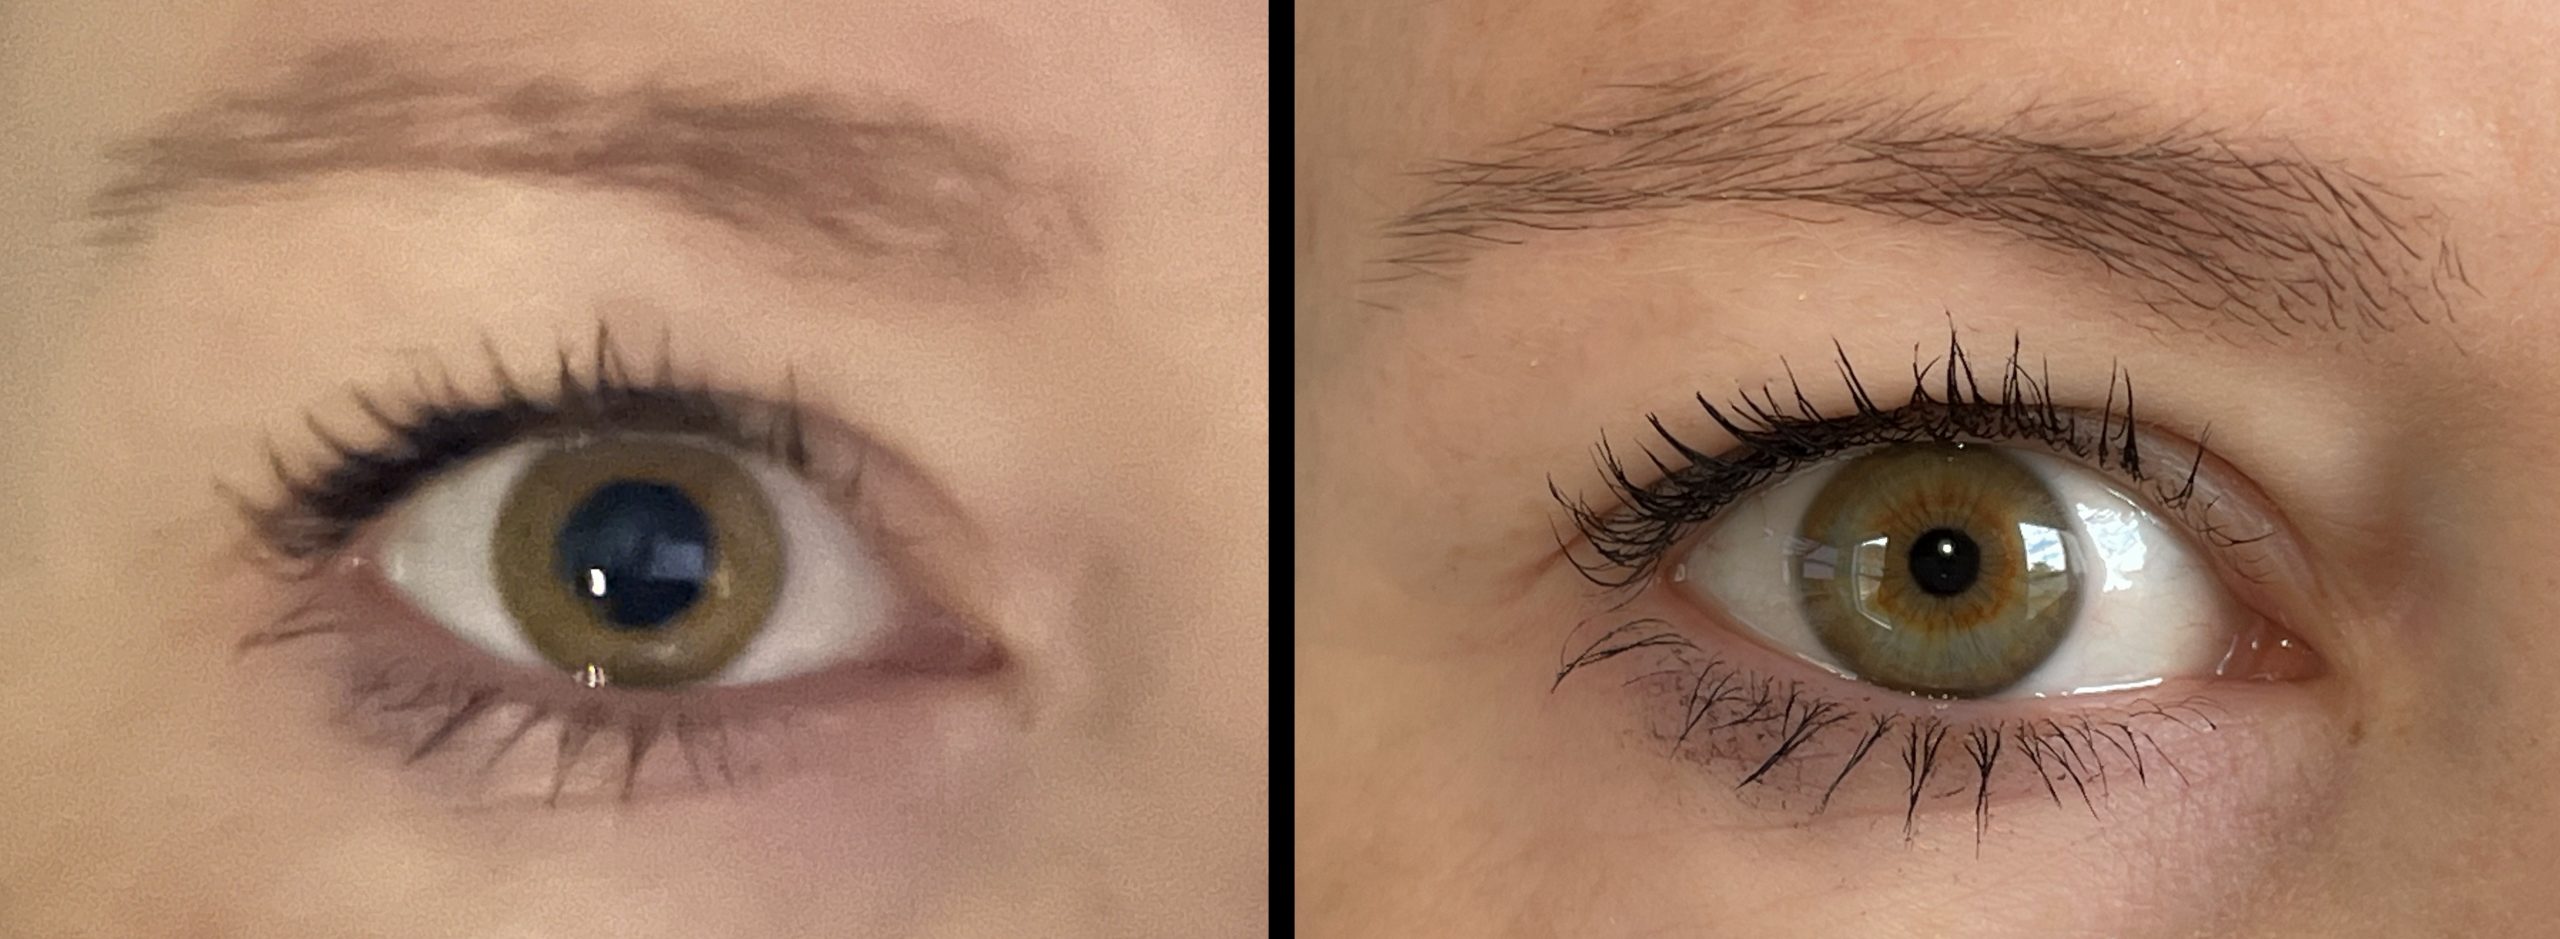
Eye photographed in dim and bright light to show change in pupil size.
Eye on the left photographed in dim light.  Same eye on right in bright light.  Note how pupil on left is dilated (larger) in order to pass more light through the lens.

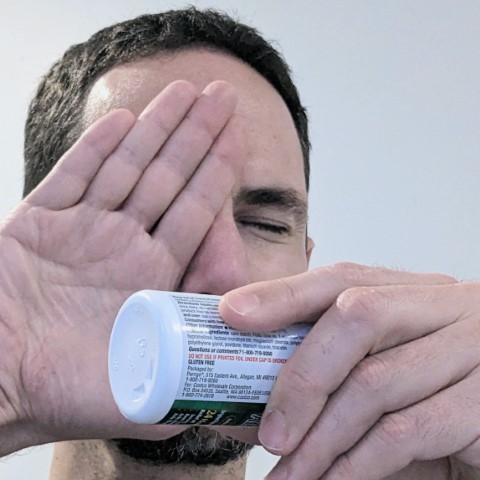
You can test this yourself:  Find some small print and bring it so close to your eyes that it becomes blurry.  (If your eyes are so young or flexible that bringing it right up to your eyes doesn’t make it blurry, take it into a darker environment so that your pupils dilate.)  Now close one eye, and with the other one look at the text through a pinhole opening held right in front of that eye.  You can make a literal pinhole by punching a tiny hole in a piece of paper, or you can create one by closing your fingers together leaving only a tiny opening.  Now you will be able to clearly see what was out of focus before.

Using a hand to form a pinhole aperture in order to read fine print without reading glasses.
David Bookstaber actually uses this trick to read fine print when no reading glasses are handy.

The problem with pinholes is that they don’t admit much light.  So everything you look at through a pinhole will be in focus, but without adequate illumination it might be too dim or low-contrast to read.

What does this have to do with UI themes?  Light Mode puts out more light, which causes your pupils to contract, which increases the depth of field of your lens and allows your eyes to focus on objects that are closer.  For any given display brightness, there will be a distance at which text is too close for me to read without glasses or eyestrain in Dark Mode but where the same text will still be readable without glasses in Light Mode.

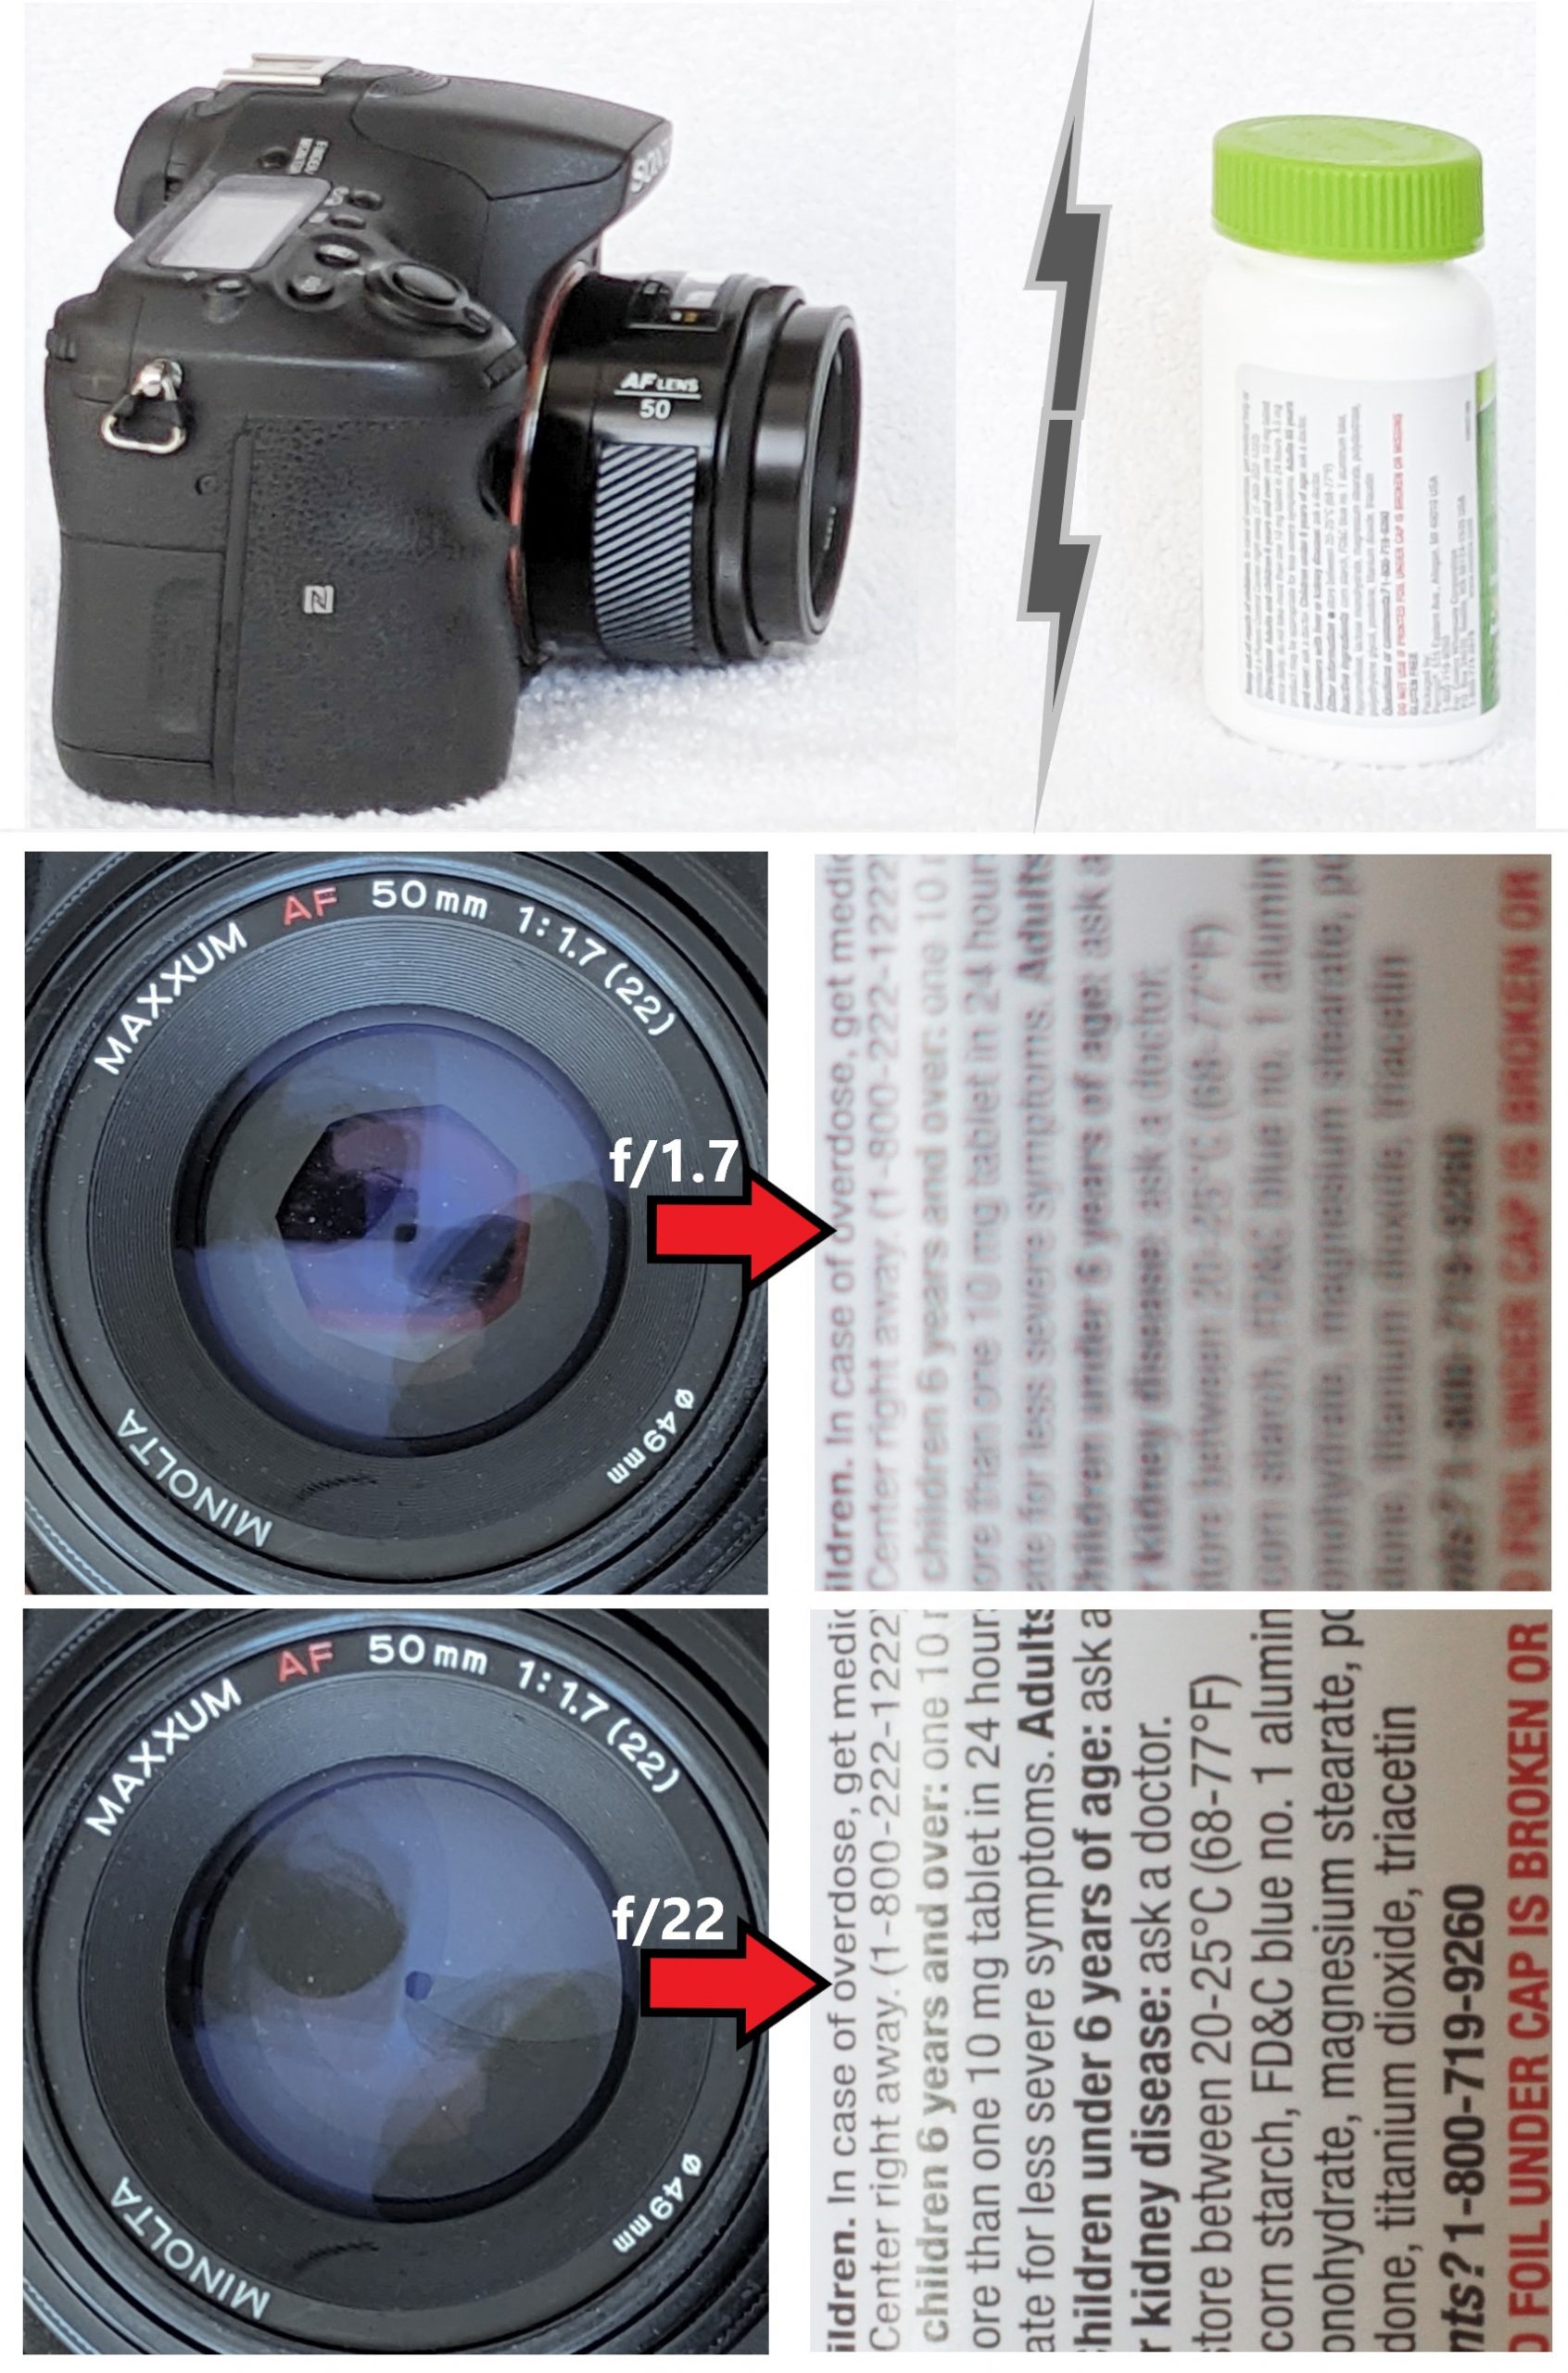
1. The following illustration demonstrates this.  I set a pill bottle just inside the closest distance this lens can focus at maximum aperture (f/1.7), so the text is blurry (second row of photos).  Then I closed the aperture as tight as it goes (f/22) and took the photo again (third row of photos).  Now the text is clear.  The cost: To get the same exposure required a shutter speed of only 1/640 second at maximum aperture, but 1/4 second at minimum aperture.

The same fine print photographed at f/1.7 and at f/22, showing how a smaller aperture increases depth of field.
Photos of a pill bottle sitting inside the minimum focal distance of a lens.  At wide-open aperture the text is blurry.  At minimum aperture the text is legible.  (The photo of the lens aperture in the second row is slight closed to f/2.8 because wide-open the iris doesn’t show at all.)

Software Engineering

First published in my newsletter, September 29, 2023.

I’m writing a book on ballistics, based in part on my work on ballistipedia.com, and I got to the point that I wanted a raw ballistic calculator to create examples. I found a public implementation of a well known calculator in (programming language) Python and decided to start with that.

Nothing gets you up to speed on software engineering tools like having (a) a project you want to complete and (b) existing code to work from. In this case the existing code used a lot of Cython, which is a hybrid of Python and C that I have been meaning to pick up for a long time. I have been using Python more than any other language for the last six years. But I began coding in C more than thirty years ago. So why did I end up using Python if C is still relevant?

Some features of Python:

  1. It’s a high-level language that encourages concise and readable code.
  2. It’s the most popular programming language. Whatever you want to do, you can probably find existing (and free) Python packages that get you most of the way there. For example: I recently needed to scrape a bunch of data from a website. Bing’s chatbot recommended a package called selenium, and in less than an hour and 30 lines of Python I was done.
  3. It is interpreted, not compiled. This makes it fast to write and easy to prototype in, but it also means the code runs relatively slowly.

In the past decade computers have gotten so fast that the last point is usually not an issue. Lots of production systems are running in Python. But when you realize how much slower Python runs this is surprising: As an example, I just made a Cython version of a simple statistical simulation I had written in Python. The Cython version can run 10 million simulations in 15 seconds. In the same time, the Python version completes only 75 thousand simulations. The compiled Cython version is over 100 times faster!

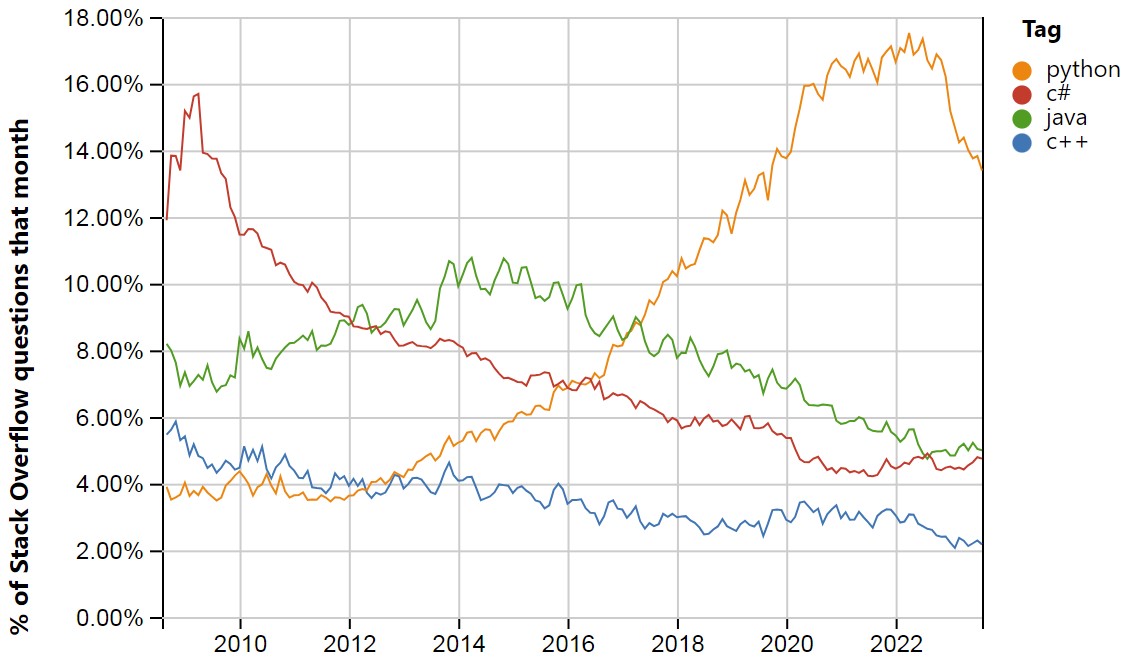
So how does a programming language that runs two orders of magnitude more slowly than the alternatives become so common? This is interesting, because Python has been around for 30 years, but its use has only really exploded in the last decade.1 The other thing that has exploded over this timeframe is the amount of excess compute – a term that refers not only to processing speed but also to storage capacity and information transmission bandwidth. A generation ago we marveled that a student calculator had more compute than the guidance systems that landed man on the moon. Today, there is so much compute in a typical smartphone that developers rarely have to worry about speed or memory. And so we use tools to build and publish apps that are hundreds of times larger and slower than necessary because (a) they’re easier and (b) it’s no longer worth the effort to make them small or fast.

Have you ever noticed the size of installation files for smartphone apps? Very few weigh in at less than 10 megabytes. Heck, the basic calculator app on my phone takes up 8MB of memory! Why? 30 years ago the same app under Windows 3.1 used 41kB of memory (that’s 1/200th the size).

Smartphone calculator app listing showing 8 MB of storage used
8 Megabytes of functionality here?

It’s not a coincidence that I didn’t use Python much earlier. Most of my work is in the finance industry. In the 1990s we could never get enough storage for market data or speed to run analyses, so we spent a lot of time optimizing our C++ code to squeeze as much as we could out of our compute resources.

In the early 2000s I still knew every detail of every available piece of computer hardware because I was working them to their limits. I still remember my excitement to get a server with two 64-bit Opteron CPUs and to break out of 32-bit memory space! The early 2000s were also the point at which we could afford to use a SQL database instead of handling every detail of reading and writing our data to files and keeping track of exactly what was being held in RAM at each moment.

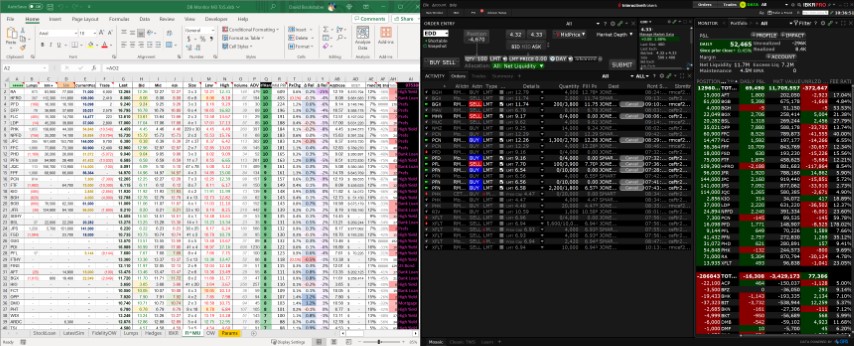
The last decade is when we could get really sloppy. With gigabytes of RAM on every computer it’s usually possible to keep everything of interest in memory; no need for a database. Where previously I used C++ or C# to build production systems for trading and portfolio management, computers are now so fast that I actually built and run my most recent system in Microsoft Excel! I’m not kidding: Here’s a screenshot of Excel (left) consuming realtime data and generating portfolio analysis next to an Interactive Brokers Trader Workstation (right):

Microsoft Excel consuming realtime market data beside Interactive Brokers Trader Workstation
These days, real quants can make everything work in Excel

1. TIOBE publishes data on programming language popularity. Stack Overflow is another good indicator, which is where I got this chart:

Stack Overflow question-share trends for C++, Python, Java and C#

Where Do Trading Profits Come From?

This is a question I first encountered in college, where it was tinged with idealistic indignation at this glaringly capitalist phenomenon. Since I have continued to work in the industry I regularly encounter it in various forms, and it’s worth explaining in detail.

Capital markets are institutions that match capital suppliers (monied investors) with capital demanders (typically, businesses that need money to make money). Demanders attract suppliers by offering to pay them for the use of their capital. For example, a business might sell standardized instruments like stocks (which confer ownership and may pay dividends) or bonds (which pay interest). Secondary (trading) markets for these instruments tend to be pretty efficient, which means that on average there’s little money to be made by trading one stock or bond for another. In fact, trading in secondary markets is roughly a zero-sum game: every dollar earned by one trader comes out of the pocket of another. Which is why investors are encouraged to buy and hold, and why active trading tends to be a money-losing activity.

But there are enterprises that make large and consistent profits by actively trading stocks and bonds. This leaves many laypeople understandably confused: They are warned that if they actively trade they should expect to lose money, while professional trading operations consistently win money. So is trading profitable, or not?

In healthy capital markets, there are three legitimate ways to make money by trading: Providing liquidity, information, or insurance. (There are also some illegal ways, like manipulation.) Nearly everything the trading industry sells, and nearly every fee it collects, traces back to one of those three services. And if you’re not providing one of those services when you trade, then you’re probably paying for them.

The first service, liquidity, is the ability to conveniently value and exchange assets. The owner of a liquid asset knows at all times what the asset is worth, and can quickly sell the asset for close to its full value. Liquidity is the foundation of capital markets: investors supply a lot more capital when they are confident that they can get it back when they need it. Without liquid markets the gears of capitalism can grind to a halt. But liquidity doesn’t happen in a vacuum, and the suppliers of this metaphorical lubricant are paid for it. In the old days of centralized stock exchanges you could point to the front-line liquidity suppliers: specialists staffing the exchange stood ready to buy and sell stocks. They posted the prices at which they would buy (bid) or sell (offer) shares, and the cost of their service was baked into the difference between the bid and offer prices. Today’s stock exchanges are more complex and less centralized, but the fact remains that they depend on liquidity providers.

Another layer of liquidity waits outside the exchange to step in when the demand for liquidity exceeds what market makers can provide. Imagine that someone wants to sell a large amount of stock. As they begin to sell, the routine supply of buyers at the market price is exhausted – nobody is left willing to buy at that price. But lower the price and the stock begins to look like a bargain, which brings in a new supply of buyers. A trader who stands ready to buy when others are desperate to sell is supplying exactly what is scarce in such moments, and is paid for the service. Liquidity provision is a source of profit that can persist even in efficient markets – compensation for storing money and accepting risk when other participants are scrambling for cash.

The second service is information. Traders with special information indicating that a stock is undervalued can buy it, and if the information is correct then they will profit as the stock’s price moves towards its fair value. For example, an analyst might conclude that a company’s new product will be more successful than expected, and that its stock price has not increased to reflect that. If the analyst buys the stock, that purchase pushes the price up marginally – communicating the information to the market, but not in a way that produces any immediate profit for the analyst. The analyst’s profit is most likely realized when the information is proven correct: If the company’s earnings beat the consensus, its price will jump and the analyst can then sell for a profit. The difficulty is that this kind of edge tends to consume itself: public information is already incorporated into market prices. To make money trading on information you have to find a proprietary source – famous ones have included counting shipping containers moving through freight hubs. And information no longer pays once the source becomes widely known or available: the market price simply moves to incorporate it without any friction that a trader can exploit.

The third service is insurance, or the assumption of risk for a premium. This is subtly built into the prices of all investments, but risk can also be explicitly traded via derivative contracts like futures and options. Someone who wants to limit potential losses on a stock can buy an option. In that transaction, the option seller pockets the option’s premium in exchange for carrying its risk.

So who gets paid for providing liquidity, information, and insurance? In theory, anyone can, but it’s a competitive market that has grown increasingly dominated by professionals with tools and skills not available to lay investors. When you see a stock price dip can you tell whether the move was caused by someone demanding liquidity and not somebody trading with special information? Can you precisely calculate the “insurance” (risk) component of an asset’s price? Professional traders can. Or rather, any trader who can’t won’t stay in business for long.

It is worth stepping back to see what all of this accomplishes. In the normal course of events capital markets are like a nuclear reactor, pooling capital and exchanging risk to create heat that powers the economy – and yes, like a reactor, they occasionally melt down. But without the concentration and free exchange of capital and risk no heat is generated and economic development is stagnant. The profits earned in trading are what the economy pays to keep that reactor running, and, stripped to their essence, they are payment for just three things: liquidity, information, and insurance. If you’re trading without providing any of those services, then you’re probably paying for them.

Streaming Real-Time Market Data into Excel: Why RTD Beats Polling an API for Analysts

Financial analysts live in Excel, and I’m no exception. Python (enhanced with pandas, numpy, etc.) is more powerful, but sometimes the convenience of having a complete data set exposed in Excel is worth the tradeoff. And modern Excel is strong enough to run a realtime trading dashboard. I’ve done that for years now. And a few years ago I discovered that it’s really strong if you use the right tools. One of those is Microsoft’s Real-Time Data (RTD) protocol, and even though that was introduced to Excel almost 25 years ago I only recently discovered it and began to unlock its power.

Before I moved my dashboard to RTD, I pulled positions and account values via DDE (Dynamic Data Exchange), which is a protocol introduced 40 years ago! Ancient doesn’t always mean obsolete, but in this domain DDE hit its limits long ago and has been (appropriately) deprecated by Microsoft. Before I abandoned it, getting DDE to reliably feed data into Excel required jumping through hoops. Just establishing a connection between Excel and the broker’s API required starting a separate Java bridge process. The spreadsheet receiving the data had to be running in its own Excel process because every DDE update would lock the GUI. And if you happened to touch that workbook at the wrong moment in its update cycle it would lose the connection or crash completely. So on top of the Excel dashboard I wanted to work in, I had to start a separate “feeder” Excel workbook and a Java bridge. And the result wasn’t literally realtime – data arrived in my dashboard when the feeder was able to push it, which could be as frequently as every 10 seconds – but that was adequate for my needs.

And kludgy. But that’s the way all Excel data feeds were: You had to shoehorn cell updates into a system not designed for continuous calculation. Anyone who has added a “volatile” function to a heavy workbook knows this peril – or gives up – because every update means a global recalculation. The countermeasures are familiar hacks: polling loops, event handlers, lots of Visual Basic, etc.

I first saw the convenience of RTD when I used it to stream market data from ThinkOrSwim. Every other data source used an Excel add-in. ThinkOrSwim just magically appeared when needed. =RTD("tos.rtd",, "LAST", "SPY") would update the last trade price of SPY multiple times per second (once Excel’s default two-second RTD throttle is dialed down). But how? Unlike add-ins, you couldn’t even tell it was available until you asked Excel for it. It never consumed a measurable amount of CPU, never blocked the GUI, never lagged, never crashed. And that function: start to type “=RTD” and Excel reveals it’s a native function. This was a realtime data feed mechanism built in to Excel!

Once I began to dig into RTD I couldn’t stop. The interface could hardly be more simple: an RTD service only has to implement six methods and register itself as a Windows component. The mechanism was elegant: Excel tells the RTD server what topics the user has requested (e.g., “the last trade price of SPY”), the RTD server tells Excel when there is new data on that topic, then Excel asks for the data as soon as it can receive it. This was the trick to avoid blocking or crashing Excel, while feeding it data updates as fast as possible.

Implementing an RTD server properly turns out to be trickier than one might expect: You have to be very careful about thread management and subscription accounting. And you have to get the RTD server talking to the data source through whatever API is on the other end. But I think it’s worth the trouble: My Excel trading dashboard now gets realtime data through virtually invisible servers that have withstood all my attempts to break them. For example, I streamed 3,000 stock quotes through the market close on a busy day, and Excel just kept working. Once I’ve seen how it can be done right, I can’t go back.

Early Memories

My body was born 50 years ago. I know this not only because my parents told me, but also because the government decided its business includes tracking and certifying exactly when, where, and of whom people are born.

My body bears the scars and wear of 50 years of life. The first half of that period it was growing. Then it stopped growing and started down a predictable path of degeneration. (Presbyopia appeared within the last decade, followed by the beginnings of detectable osteoarthritis.)

My mind also bears the scars and wear of 50 years of life. I can trace paths backward in time, but my ability to do that is also only going to degrade as it ages. My memory (like that of most people) is not continuous. I have snapshots of varying length, clarity, and detail. Looking back in time is like turning around and finding most of the path you walked submerged in a dark body of water. The memory snapshots are like stepping stones that have not yet sunk from view.

How far back can I see?

My earliest memory is from just before I reached my second birthday. What I remember is looking out a window where we lived and seeing a snowplow a few houses up the street that was stuck. I was upset and wanted the truck to get help. I was placated when my father said he would go help it. (How can I be confident in this memory? The visual details in my mind are limited, but I am certain I was looking downwards and to the left and the plow was 3-4 houses up the street heading away. Cross-checking with my parents: at the time we lived on the second story of a house that had windows tall enough for a 2-year-old to see out. My father remembers the incident and agrees with the orientation and distance of the plow. Public records note two extreme blizzards in the month before my second birthday.)

Memories that I would call visually “complete” begin by age 4, which I can tell because they occurred around a house we left in my fifth year. Here are some of the more vivid ones:

Rattlesnake in the street: I was playing outside and my Mom ushered me into the house saying there was a rattlesnake and it was dangerous. I watched from a window as my Dad and five other men from the neighborhood formed a loose circle around it, right in the middle of the street. They were armed with shovels and I could see a few take jabs at the snake, but otherwise they were just hanging out, talking. I was a little confused because my Mom had made it seem like a serious threat, but it looked like the men were treating it as more of a social gathering. I finally got bored of watching so don’t know how that ended.

Want to learn violin? My Mom was lying on a bed reading a book. Out of the blue, she looked up and asked me if I wanted to take violin lessons. (What is a 4-year-old in the pre-computer-game era going to say: “No, I have too many other commitments?” Of course I’d like to try a new activity!)

You only get soda if you can do it right: A local kid had a 2-liter bottle of soda. He offered to share it with anyone who could drink without backwashing. I don’t remember the words he used to explain it, but basically if you could pour or sip without putting the whole opening in your mouth, you could drink; if not you only got to watch. He demonstrated, and then invited others to drink. I was so relieved when my lips proved coordinated enough to get soda. I felt bad for another boy failed and was denied.

Coding Agents Grow Up

For years, programming something new followed a predictable, exhausting rhythm: write some code, hit a wall, and then disappear into a forest of documentation and StackOverflow tabs to find the trick to get it working. In 2025, that era ended for me.

Today, AI code assistants take so much drudgery out of development and debugging that the work has become mostly gratifying and rarely frustrating — the opposite of how programming was in the Before Times.

Between my work and my side interests, I often feel like I live in Visual Studio Code (VSCode — a popular open-source development environment). Early in 2025 I subscribed to GitHub Copilot, which integrates AI coding assistants into VSCode. At $10/month it’s a phenomenal bargain that offers software developers an easy way to loop in the latest models from OpenAI, Google, and Anthropic. Now when I’m trying something new (like this little project I did for fun) I can mostly stay in VSCode and work with an AI assistant that has mastered all of the documentation.

As mentioned elsewhere, my most significant side project in 2025 was helping Ukrainians develop an open-source ballistic calculator (pyballistic) in Python and Cython. I polished that off at the end of September.  By that point I had begun to spend more time with Github Copilot, and the capabilities of its latest models gave me enough confidence and support to tackle what would have previously been an absurdly ambitious project for my day job: an Excel Real-Time Data (RTD) server for the Interactive Brokers API.  (This RTD server feeds live market data, positions, and orders directly into Excel using native Excel formulas.) After two months of working seven days a week on that, I had a beautiful piece of software so solid (and validated every build by over 800 unit tests) that I had begun to use it in live trading operations.

Early Childhood Development

Watching these models mature over the last year has been like watching a child grow up.

Tell a child, “Clean your room.” First they’ll spend more time arguing than it would take to just do it. When they finally declare the task “done,” you might find a few toys picked up but most of the mess still there. Emphasize that “clean your room” means everything and you might find the floor clean but everything shoved under the bed.

Claude v3 was notorious for hacking shortcuts. Ask it to fix a failing test and it might just replace the test logic with a “return true;” statement. Claude v3.5 wouldn’t be so brazen, but it was still prone to hack the example rather than the task. GPT-4 and Gemini v2 would enthusiastically announce completion without checking their work. Like the child who picks up two toys and concludes that his room must be clean, even though the mess is visible from outside the door.

The teens came quickly: Claude v3.7 and its contemporaries would often spend more effort arguing that its failure was actually success than it would have taken to do the work correctly.

More recent models have become more likely to keep checking and working until they succeed. Performance of the latest models is still wildly variable: a model that astonishes me with its apparent skill one day may choke on something relatively simple the next. But they are getting more consistent. And they are definitely getting more intelligent.

What is intelligence?  It becomes easy to see when you’re doing hard work with different models. One of the neat things about Copilot is that you can choose to watch the model at work. They all think “out loud,” meaning you can read their chain of thought to understand how and why they do things. When it’s not having an off day, Claude Opus is intelligent.  Given a problem:

  • It can more reliably identify what matters.
  • It has a better sense of what to look at and what to ignore.
  • It produces better assessments of what’s possible and makes better plans to get there.
  • It knows when to persist and when to change directions.

These are some of the things that separate a junior developer from a more experienced one. They are also qualities that characterize more intelligent people.

Let me show you. Have you ever wondered what it’s like debugging software? Well, debugging is one thing the newer models can usually do as well as a good human programmer. In fact, they can do it better because they can run the process faster and interact with the code more directly. Below I pasted a transcript of Claude working to find and fix a tricky bug in my RTD server. This could just as well have been a transcript of my thoughts if I had to debug it. But whereas this would have been a draining hour+ distraction for me, the Claude instance cranked this out in minutes.

Continue reading “Coding Agents Grow Up”